

Local models
Nod can use a model that runs on your own computer, or on any server with an OpenAI-compatible API. Model requests then go only to the address you enter, and a local model costs nothing per request.
Local models work in the desktop app, source installs, and self-hosted servers.
The model server must be reachable from Nod's server. On a remote install, localhost refers to that server; inside Docker, it refers to Nod's container.
Before you start
Section titled “Before you start”You need two things from the model server:
- A model that supports tool calls. Nod does all its work through tools, so a model without them can only chat.
- At least 64,000 tokens of context. Nod's instructions and tools take about 20,000 tokens before your first message. Most servers start with 4,096, and some cut Nod's instructions off without an error.
Set up your server
Section titled “Set up your server”-
Install Ollama and pull a model that supports tools. On ollama.com, filter models by Tools.
Terminal ollama pull gpt-oss:20b -
Start Ollama with a larger context. In the Ollama app, set Context length in Settings instead.
Terminal OLLAMA_CONTEXT_LENGTH=65536 ollama serve -
Use the address
http://localhost:11434/v1in Nod.
Nod reads each Ollama model's details. It lists only models that support tools, sends images to vision models, offers the model's thinking levels and uses its context length.
- In LM Studio, download a model that supports tools.
- Load it with Context Length set to 65,536 or more.
- Start the server from the Developer tab, or run
lms server start. - Use the address
http://localhost:1234/v1in Nod.
With LM Studio 0.4 or later, Nod reads each model's details. It skips embedding models and models not trained for tool use, sends images to vision models and uses the context length the model is loaded with, so the model list shows when that's too small.
-
Start vLLM with tool calls on. Choose the tool call parser that matches your model.
Terminal vllm serve <model> --max-model-len 65536 --enable-auto-tool-choice --tool-call-parser <parser> -
Use the address
http://localhost:8000/v1in Nod. If you started vLLM with--api-key, add that key too.
-
Start llama.cpp's server.
--jinjaturns on tool calls.Terminal llama-server -m <model>.gguf -c 65536 --jinja -
Use the address
http://localhost:8080/v1in Nod.
Connect Nod
Section titled “Connect Nod”- Open Settings → Models, then select Add server next to OpenAI-compatible. During onboarding, select More providers, then Your own server.
- Check the Server address. Nod fills in Ollama's address,
http://localhost:11434/v1. If you leave out/v1, Nod tries it for you. - Add an API key only if the server needs one.
- Select Save connection, or Connect during onboarding.
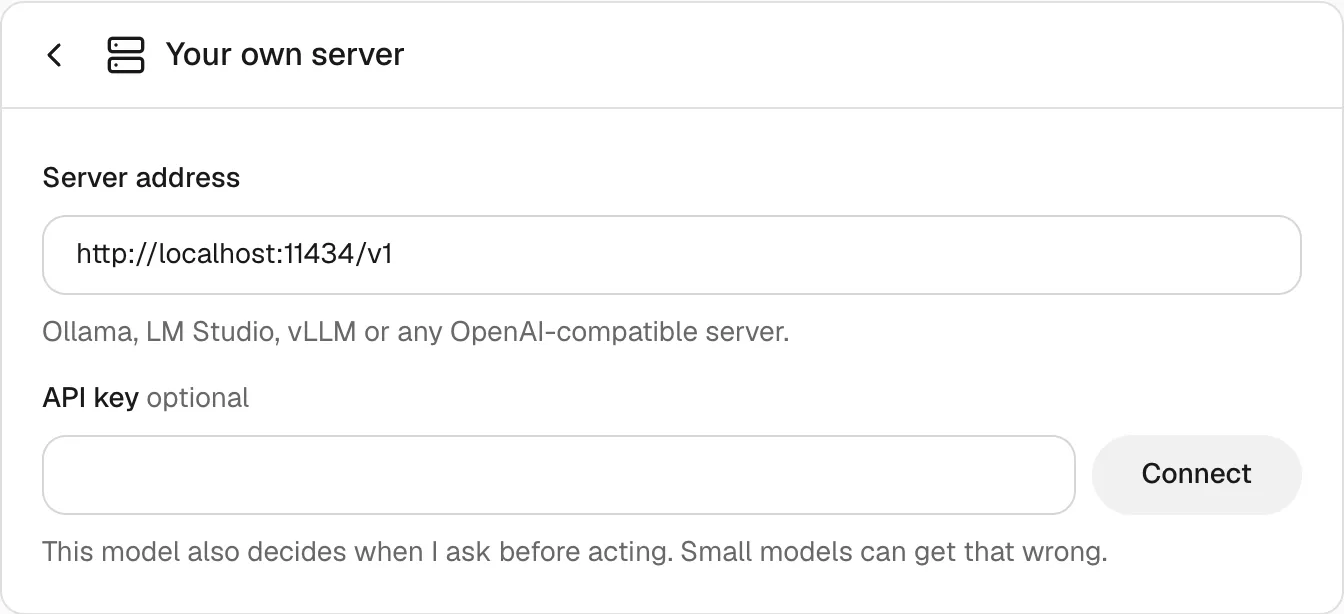
Nod checks the address by listing the server's models. The connection shows the server's host, such as localhost:11434. If you haven't chosen a model yet, Nod selects the server's first one. To switch, open Settings → Models and choose a model.
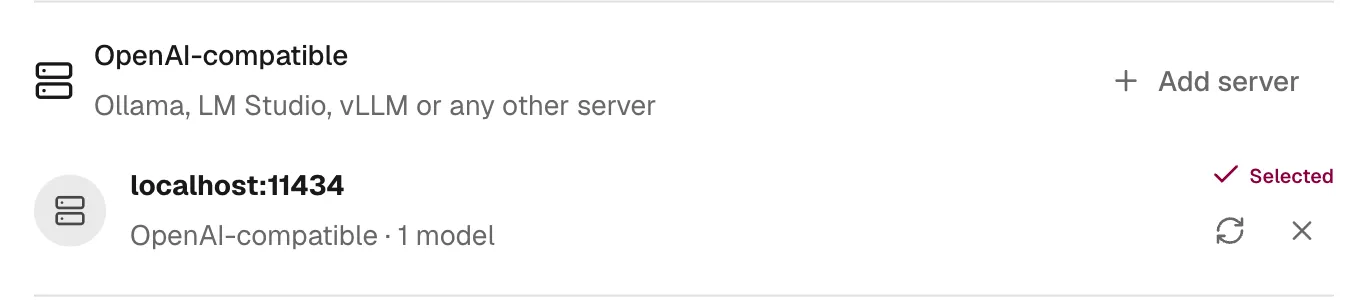
After you pull or load another model, select the refresh button next to the connection. To change a server's key, add the same address again: Nod updates that connection instead of adding a second one.
Set the server in .env
Section titled “Set the server in .env”In a source install or self-hosted server, you can set the model server in .env instead of in the app. It then shows Server settings in Models. Remove OPENAI_COMPATIBLE_BASE_URL to remove this connection.
LLM_PROVIDER=compatibleOPENAI_COMPATIBLE_BASE_URL=http://localhost:11434/v1OPENAI_COMPATIBLE_API_KEY=LLM_MODEL=gpt-oss:20bLeave OPENAI_COMPATIBLE_API_KEY empty if the server doesn't need a key, and LLM_MODEL empty to use the server's first model. After editing .env, apply the configuration change. If the server isn't running when Nod starts, start it and select the refresh button next to the connection.
Other OpenAI-compatible services
Section titled “Other OpenAI-compatible services”For services listed in Models, such as Groq, Together AI, and DeepSeek, use the named provider connection. It includes the provider's model capabilities and prices.
Use an OpenAI-compatible connection for other hosted services that offer this API. Enter the service's address and your API key.
Nod lists every model such a service returns, including ones that can't chat. Pick a chat model that supports tools.
What changes with these connections
Section titled “What changes with these connections”| Area | With a local or OpenAI-compatible model |
|---|---|
| Spending | Nod doesn't know the server's prices, so it records each request at $0. That usage doesn't count toward the monthly limit or task check-ins. A paid service still bills you. |
| Images | Ollama and LM Studio models that support vision get screenshots and images. Models on other servers get text only. |
| Thinking levels | Only Ollama models offer them. Other servers use the model's own default. |
| Decision checks | Your selected model handles confirmation replies and email checks unless TYPESAFE_API_KEY configures a decision model. See Decision checks. |
| Background work | Memory upkeep and other background work use your selected model. |
| Where requests go | Model requests go only to the address you enter. Web search, websites, your apps and chat channels work as before. See Your data and privacy. |
| Where your key goes | Keys saved in Models are encrypted. Keys from .env stay in server configuration and memory. The server adds the key to requests. See Where your keys go. |
Troubleshooting
Section titled “Troubleshooting”| Problem | Fix |
|---|---|
| Nod couldn’t list this server’s models | Check that the server is running, and that the address and API key are right. curl http://localhost:11434/v1/models should list your models. |
| This server has no models Nod can use | Nod needs a model with tool support, and from Ollama it lists only those. Pull or load one, then try again. |
| Nod ignores your request, forgets its tools or repeats itself | The context is too small. Raise it to 65,536 or more and reload the model. |
| A new model doesn't appear | Select the refresh button next to the connection. |
Can’t load its models next to a server set in .env |
Start the server, then select the refresh button next to the connection. |
| Remove it and add the server again | Nod can't read the connection's saved settings. Remove the connection, then add the server again in Models. |
| Nod asks before almost everything, or acts without asking | The model is too small for the trust check. Switch to a larger model. |